How law firm Gilbert + Tobin governs and scales AI with OpenAI
See how Gilbert + Tobin combines CEO-led commitment, rigorous governance, and human accountability to scale ChatGPT Enterprise and Codex across the firm.
The Federal Aviation Administration (FAA) released 20 pages of training materials concerning the collection, processing, and analysis of biological evidence following fatal aviation accidents. The…
Read More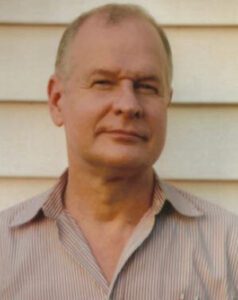
Larry W. Bryant was a UFO researcher, writer, and government transparency advocate who pursued federal records through the Freedom of Information Act (FOIA). His work…
Read MoreSee how Gilbert + Tobin combines CEO-led commitment, rigorous governance, and human accountability to scale ChatGPT Enterprise and Codex across the firm.
ChatGPT can now connect to trusted healthcare data, helping clinicians securely access patient context, medical research, and more.
Astra is the first OpenAI model to meet the Critical cybersecurity capability threshold under the Preparedness Framework, with stronger safeguards for release.
Basis, Clay, and Exa Labs use AI agents to improve onboarding, account management, and developer integrations. See what enterprise leaders can apply.
arXiv:2608.28594v1 Announce Type: new Abstract: Conversational analytics systems assume the user already has a well-formed question, leaving a non-expert facing a blank query box on an unfamiliar enterprise schema. Commercial 'proactive' tools narrow this gap only by detecting statistical anomalies over analyst-curated metric layers, and academic next-question recommenders depend on query logs that a fresh…
arXiv:2608.28593v1 Announce Type: new Abstract: With the increasing development of AI regulatory frameworks, ensuring that artificial intelligence systems, particularly generative models, operate in accordance with legal and ethical standards has become a critical priority. Existing proposals for AI alignment and value-guided behavior, however, face some limitations. Approaches such as Constitutional AI depend on human supervision,…
arXiv:2608.28592v1 Announce Type: new Abstract: Large language models (LLMs) achieve high scores on medical knowledge examinations, yet real-world oncology is not a knowledge test--it is a sequence of guideline-pathway choices, escalation judgments, and commitments under uncertainty. Existing benchmarks largely measure factual recall, leaving open whether frontier LLMs share decision-path blind spots that combining models cannot…
arXiv:2608.28591v1 Announce Type: new Abstract: Recent advancements in AI are helping scientists achieve breakthroughs in fields such as mathematics, medicine, and materials sciences. New evaluation datasets for AI models contribute to such advancement in AI. In the STEM domain, frontier models have consumed most of the available online data, creating the need for human-created datasets…
arXiv:2608.28590v1 Announce Type: new Abstract: Large Language Model (LLM) agents have shown promise for automating data-science workflows, yet their end-to-end performance depends critically on the agent harness that represents tasks, manages execution state, constrains output artifacts, and provides evaluation feedback. Existing data-science agents often leave this harness implicit, making results difficult to reproduce, compare, and…
Fertilizer is crucial for the global food supply, but making it uses a lot of energy and produces a lot of emissions. Some companies hope microbes can help. A growing body of research shows that seeding the soil around a crop’s roots with beneficial microbes can help feed the plant, providing crucial nitrogen to help…