A model guide for the GPT-6 family
Learn how startups can choose GPT-6 models, tune reasoning effort, improve prompts and skills, coordinate tools, and prepare workflows for production.
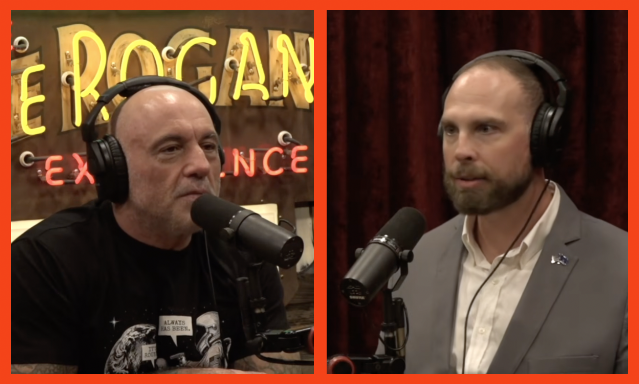
Date of interview: Oct 2026Now Joe Rogan had an interview with UFO gov whistleblower David Grusch and things really got interesting as he revealed some…
Read More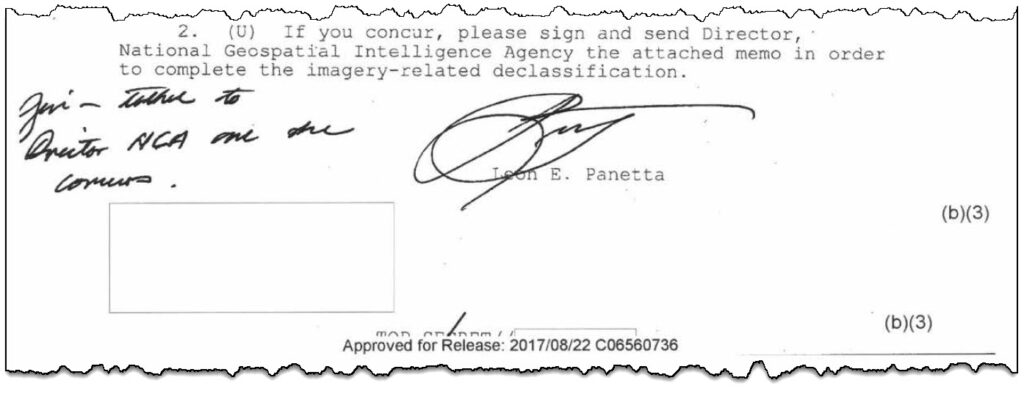
A newly obtained Central Intelligence Agency release provides a detailed look at the material prepared inside the U.S. government for the public rollout following the…
Read More
The 1980 presidential campaign between Democratic President Jimmy Carter and Republican challenger Ronald Reagan became the subject of a political controversy after it was revealed…
Read MoreLearn how startups can choose GPT-6 models, tune reasoning effort, improve prompts and skills, coordinate tools, and prepare workflows for production.
arXiv:2610.00025v1 Announce Type: new Abstract: Agent harnesses increasingly want to run small language models (SLMs) on the microtasks around a frontier large language model (LLM) planner: auto-approving shell commands, writing memory, selecting tools, ranking past turns. We ask whether off-the-shelf SLMs meet practitioner-defined thresholds and, when they fail, why, and whether quantization changes the answer.…
arXiv:2610.00018v1 Announce Type: new Abstract: Role-specialized QA pipelines increasingly pass rationales from a reasoner to a verifier, but it is unclear what this message actually buys: better answers, stronger support assessment, or a new failure surface. We introduce a message-intervention diagnostic that fixes the evidence and candidate answer while varying only the rationale passed across…
arXiv:2610.00015v1 Announce Type: new Abstract: Large-language-model agents can propose and execute actions, but proposal, authority, dispatch, verified external effect, and serving promotion are different claims. We present Praxa, an agent harness that represents these states explicitly through deterministic admission, brokered execution, external read-back, reconciliation, and reviewed promotion. We report four evidence lanes. First, an author-run…
arXiv:2610.00012v1 Announce Type: new Abstract: LLM agents increasingly act through modular systems, such as order, payment, inventory, and shipment services, where actions in one module change which transitions are valid in another. Standard world models usually fit observational traces, but this is not the quantity needed for intervention-time planning: a trace may show that payment…
arXiv:2610.00010v1 Announce Type: new Abstract: Long-horizon language agents increasingly rely on external memory as a frozen world model, yet current memory systems are usually judged only by task success or token cost. We argue that the missing object is the shape of memory use: under finite context and repeated retrieval, agent memory can concentrate on…
On an afternoon in Seoul in March 2016, I watched a program I helped build put a stone on the fifth line of a Go board in what looked like a gift to its human opponent. Move 37 in game two of the five-game match looked so absurd that some commentators thought it was a…
This week, I officially signed up for an unusual competition. One that rewards competitors for getting younger. I recently turned 40, and I don’t need reminding that both time and my chronological age only tick forward. But this game is focused on competitors’ biological ages—figures that are meant to provide a better way to measure…
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. A new contest pits competitors against each other in a race to biological youth —Jessica Hamzelou This week, I officially signed up for an unusual competition. One that rewards competitors for…
Enterprise AI is no longer a future ambition. It is in full operational flight. Model capabilities are advancing faster than most organizations can absorb, while the cost of performance continues to fall. Globally, AI investment is set to reach $2.5 trillion in 2026, up 44% from the previous year. For many enterprises, this investment has…