5 Proven Techniques for Token Compression and Prompt Optimization
Reduce costs, improve response quality, and build leaner AI applications with these prompt engineering strategies.
Date of interview: Oct 2026Now Joe Rogan had an interview with UFO gov whistleblower David Grusch and things really got interesting as he revealed some…
Read More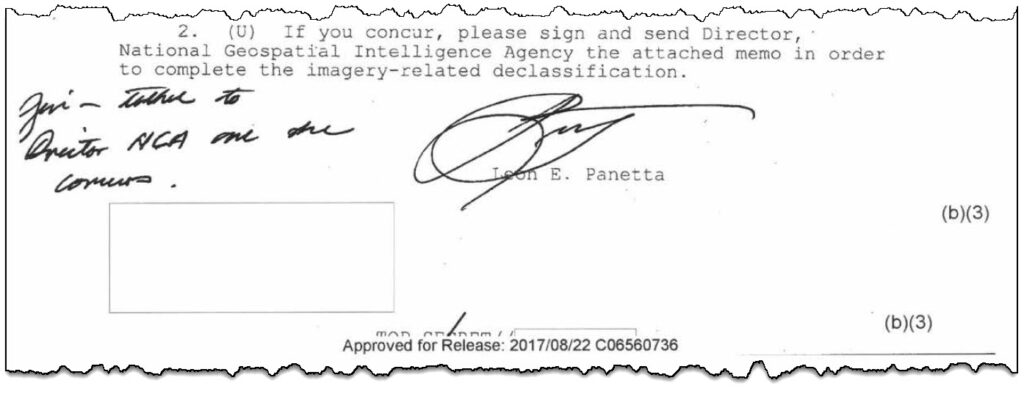
A newly obtained Central Intelligence Agency release provides a detailed look at the material prepared inside the U.S. government for the public rollout following the…
Read More
The 1980 presidential campaign between Democratic President Jimmy Carter and Republican challenger Ronald Reagan became the subject of a political controversy after it was revealed…
Read MoreReduce costs, improve response quality, and build leaner AI applications with these prompt engineering strategies.
The forward deployed engineer: is this the hot new AI career, or has the hype cycle rebranded?
This is the Python material that does not get left behind. Almost none of it is replaced by a framework later. Learn it, and keep this cheat sheet close by as a handy reference.
Learn how to use Marimo for interactive data analysis with Python, Pandas, and Altair, and turn a reactive notebook into a simple shareable dashboard.
Get work done, and have seconds added back to your life since you won't be writing second, third or — *gasp!* — fourth line follow-ups to your impeccable typed line numero uno.
Docling takes documents in whatever inconsistent format they arrive in, and converts them into one unified, structured representation that both people and AI systems can work with reliably, rather than everyone downstream having to guess at what a wall of extracted text actually meant.
Describe your data needs in plain language and turn websites into a continuous source of fresh data.
OpenAI’s agents reached a proposed solution in 88 hours. But the human research that came before, and the controversy that followed, raise a harder question: what actually counts as an AI discovery?
Ollama pulls model weights, keeps an HTTP server on port 11434, and hands any client an OpenAI-shaped endpoint pointed at your own machine. Learn how to manage, configure, and optimize using Ollama right here.
This is a summary of, and insights into, what I found digging into the recently-released Superwhisper S1 family of voice-to-text models.