A VRAM budget formula for LLM serving, and three optimization strategies mapped to the traffic patterns that trigger the OOM.
The post The KV Cache Tax: Why Inference Servers Run Out of Memory Before Compute appeared first on Towards Data Science.
Date of interview: Oct 2026Now Joe Rogan had an interview with UFO gov whistleblower David Grusch and things really got interesting as he revealed some…
Read More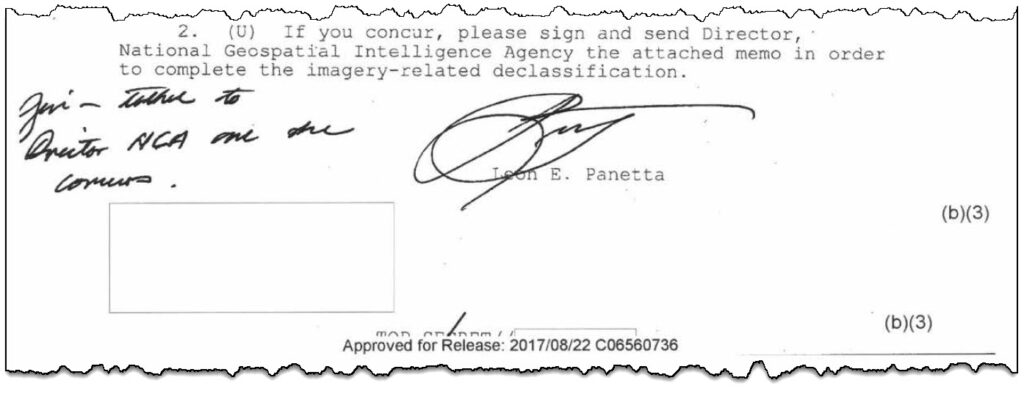
A newly obtained Central Intelligence Agency release provides a detailed look at the material prepared inside the U.S. government for the public rollout following the…
Read More
The 1980 presidential campaign between Democratic President Jimmy Carter and Republican challenger Ronald Reagan became the subject of a political controversy after it was revealed…
Read MoreA VRAM budget formula for LLM serving, and three optimization strategies mapped to the traffic patterns that trigger the OOM.
The post The KV Cache Tax: Why Inference Servers Run Out of Memory Before Compute appeared first on Towards Data Science.